近年の並列シーケンシング技術の進歩に伴い、公開されるショートリード・シーケンスデータが急増している。これを受けて、RNA-seqデータからトランスクリプトームをde novoアセンブリするための新たな計算ツールの開発が進められてきた。しかし、こうしたツールが利用可能になった現在でも、トランスクリプトームのアセンブリを一貫した工程として実行するには、ベストプラクティスへの理解を要する複雑な作業が伴う。エラー訂正、アダプター・トリミング、キメラ配列の除去といった品質管理工程を適切に実施する必要があるだけでなく、プログラム間でデータをやり取りする際に手作業でのフォーマット変換やデータ構造の変更が必要となることも多く、これらが処理のスループットを低下させる要因となっている。そこで本論文では、アセンブリ工程を効率化し、高品質なトランスクリプトーム・アセンブリを一貫して生成できるツールSemblansを紹介する。Semblansは、生のショートリード・シーケンスからアノテーション付きのコード領域(CDS)に至るトランスクリプトーム・アセンブリの主要な工程(品質管理、再構築、後処理)を統合・抽象化する。既存のアセンブリ結果と品質面で比較評価を行ったところ、テストした101件のショートリード・データセットのうち98件において、Semblansはより高品質なアセンブリを生成した。SemblansはC++で記述されており、Unix互換のオペレーティングシステム上で動作する。ソースコード、ドキュメント、およびコンパイル済みバイナリは、GNU General Public License(GPL)の下、https://github.com/gladshire/Semblans で公開されている。
インストール
依存
Semblans will install most of the dependencies it requires, but make sure you have working installations of:
- bowtie2
- jellyfish
- salmon
- samtools
- numpy
Github
#依存
mamba create -n Semblans python=3.11 -y
conda activate Semblans
mamba install -c conda-forge -c bioconda kmer-jellyfish bowtie2 samtools salmon  numpy -y

#本体 v1.0.3
wget https://github.com/gladshire/Semblans/releases/download/v1.0.3/semblans_v1.0.3.tar.gz
mkdir release
tar -xzf semblans_v1.0.3.tar.gz -C release
cd release/Semblans
export PATH=$PWD:$PATH
> ./bin/semblans --help
USAGE:
semblans [--help/-h] [COMMAND] [--config/-cfg]
[--threads/-t] [--ram/-r] [--retain/-f]
[--verbose/-v]
ARGUMENTS:
[COMMAND]
preprocess Performs pre-assembly steps only
assemble Performs de novo assembly step only
postprocess Performs post-assembly steps only
all (default) Performs all steps in pipeline
[MODE]
-1/-2, --left/--right Specifies simple mode.
Path to left/right read FASTQ(s) should follow the corresponding flags.
To specify multiple pairs of files, separate file paths with commas.
-o, --out-directory Specifies path to where Semblans should place output files.
-p, --prefix Specifies the name of the resulting assembly Semblans creates.
Directory must already exist
-kdb, --kraken-db Specifies which Kraken databases to use during removal of foreign reads.
To specify multiple databases, separate their paths with commas.
If omitted, Semblans will skip foreign read filtration
-a, --assembly Specifies an assembly for Semblans to process.
Only used during postprocessing.
-rp, --ref-proteome Specifies the reference proteome Semblans will use for
chimera detection and coding region prediction.
Only used during postprocessing.
-cfg, --config Specifies config file mode.
Path to config file should follow this argument
[FLAGS]
-t, --threads Specifies number of threads/CPU cores to employ
-r, --ram Specifies ammount of memory/RAM (GB) to dedicate
-f, --retain Prevents deletion of intermediate files in pipeline
-v, --verbose Prints all output from Semblans and sub-programs
-h, --help Displays this help screen
実行方法
Semblansは複数の外部パッケージを統合し、C++によるデータストリーミングの高速性を活用することで、前処理、品質管理、アセンブリ、およびアセンブリ後の各工程を効率化し、全自動でのアセンブリ処理を可能する。

(論文より転載)
Semblansのワークフローは、preprocess(左)、assembly(中央)、postprocess(右)の3つの連続したフェーズに分かれている。エラーの種類と、それを除去するために使用されたプログラムまたは手法も強調表示されている。
全体のプロセスを自動で進めるallコマンドと、preprocess、assembly、postprocessの1つだけ行なうコマンドが用意されている。
preprocess
ペアエンドfastqと出力を指定する。
mkdir preprocess_outdir
semblans preprocess -1 R1.fq -2 R2.fq -o preprocess_outdir -t 8
- -1/-2, --left/--right Path to left/right read FASTQ(s) should follow the corresponding flags. To specify multiple pairs of files, separate file paths with commas.
- -o Specifies path to where Semblans should place output files.
- -p Specifies the name of the resulting assembly Semblans creates. Directory must already exist
- -t Specifies number of threads/CPU cores to employ
出力例

preprocess/

all
allコマンドで全プロセスを通しで実行する場合、リファレンスプロテオーム、ペアエンドfastq、メモリ上限、CPU数などを指定する。Trinityはメモリをかなり使うので注意する。 *1
#たとえばEnsembl_plant proteomeを使う
curl -L -C - --fail --progress-bar -o ensembl_plant.pep.all.fa.gz \
'https://www.dropbox.com/scl/fi/hbvtnd9wsiwt8k7gakcmq/ensembl_plant.pep.all.fa.gz?rlkey=8cp9sn5wrt9uu4vc2pmg8xvin&st=1gesuqq0&dl=1'

#準備ができたら実行する
semblans all --verbose --threads 32 --ram 128 --retain --prefix my_assembly\
 -rp ensembl_plant.pep.all.fa -1 sample_R1.fastq.gz -2 sample_R2.fastq.gz
- -rp Specifies the reference proteome Semblans will use for chimera detection and coding region prediction. Only used during postprocessing.
- -t Specifies number of threads/CPU cores to employ
- -r Specifies ammount of memory/RAM (GB) to dedicate
出力例
assembly/01-Transcript_assembly/
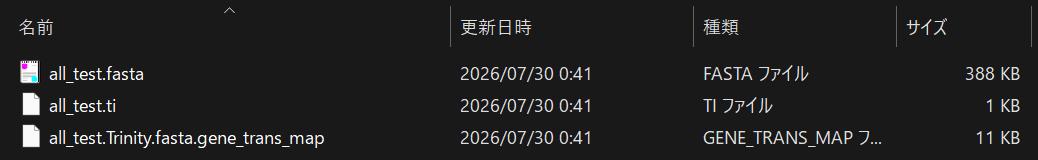
postprocess/
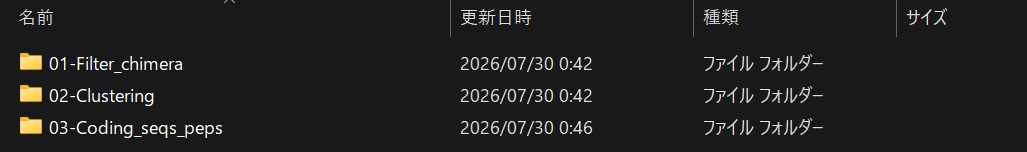
postprocess/02-Clustering/

(postprocess/02-Clustering/all_test.lc.fastaが最終アセンブリ配列)
論文より
- Semblansは、RNA-seqのショートリードからde novoトランスクリプトームを構築するワークフローで、前処理、アセンブリ、後処理の3段階から構成される。前処理では、FastQCによる品質確認に加えて、Rcorrectorによるシーケンスエラーの修正、Trimmomaticによるアダプター除去、Kraken2による外来生物由来リードの除去、過剰に出現する配列の除去を行う。
- Rcorrector (Song and Florea 2015) では、実装されているk-スペクトル(k-spectrum)ベースの手法を用いて、1塩基のシーケンシングエラーを修正する。Rcorrectorによって「修正不可能」と判断されたエラーを含むリードは、Semblansによって除去される。初期の品質解析において合成アダプター配列が検出された場合、SemblansはTrimmomatic (Bolger et al. 2014) を呼び出し、リードからそれらを除去する。
- Kraken2 (Wood et al. 2019) に実装されているk-merベースの分類手法を用いて、外来リード(異種生物由来のリード)の分類とそれに基づくリードの精緻化を行う。Kraken2データベースに対して外来リードとして分類されたリードは、データセットから除去される。前処理の最終ステップとして、2回目のFastQC品質解析で特定された過剰表現配列(配列データ全体の0.1%超を占める配列)が除去される。
- 続いて、クリーニングされたリードをTrinityでアセンブルする。後処理では、参照タンパク質とDIAMONDアラインメントしてキメラ配列を検出・除去し、Salmonで各転写産物に対するリードの支持量を推定する。結果は、その後のCorset(Davidson and Oshlack 2014)を用いた転写産物のクラスタリングに利用される。
- Corsetを用いて類似した転写産物を遺伝子単位にクラスタリングする。
- 続いて、転写産物に対して先ほどと同じリファレンス・プロテオームを対象としたBLASTP互換のDiamondアラインメントを行い、その結果を活用してTransDecoderにより最終的なコーディング領域およびペプチドのセットを予測・出力する。最後に、HMMER(Eddy 2011)を用いてPANTHER機能ペプチドデータベース(Thomas et al. 2003)に対する転写産物のアノテーションを行うこともできる。
- Semblansは、単にTrinityでアセンブルするだけでなく、キメラ除去や発現量に基づくクラスタリングなどの後処理を組み合わせ、より整理された遺伝子・タンパク質配列セットを出力する。
- SemblansはC++のデータストリーミング機能を利用し、プログラム間のデータ受け渡しを低レベルで効率化することで、処理速度とスケーラビリティの向上を図っている。
- Semblansを使って1KPプロジェクト(1000 Plant Transcriptomes)の50試料とCaryophyllalesの51試料を再解析した結果、TransRateスコア(紹介)において101試料中98試料で元の公開アセンブリより高い値を示した。内訳はCaryophyllalesで51試料中50試料、1KPで50試料中48試料であり、古いRNA-seqデータの再解析にも有用である可能性が示されている。
- Semblansは途中でエラーが出てもfinished successfullyと表示された。呼び出している外部ツールのエラー周りの例外処理が甘い可能性があるので注意する。
引用
Semblans: automated assembly and processing of RNA-seq data
Miles D Woodcock-Girard , Eric C Bretz , Holly M Robertson , Karolis Ramanauskas , Jarrad T Hampton-Marcell , Joseph F Walker
Bioinformatics, Volume 41, Issue 1, January 2025.
関連
-
よく似たゲノム情報を使い不完全なゲノム情報しか持たない種のRNA seq解析の精度を上げる自動化されたツール Necklace
- Trinityのインストール
-
超高速にRNA seqのリードカウント(定量)を行う salmon
*1 TransDecoderのランステップでPerlモジュールが見えないエラーが出たので、対応した。また、TransDecoderの使うRがみえていなかったのでパスを通した。Rのggplot2とseqLogoも必要だったので導入した。
