タンパク質間相互作用は、細胞内のきわめて多様な機能を媒介しており、そのため結合様式も多岐にわたる。近年、タンパク質構造の全体像を網羅的に把握し分類しようとする大規模な取り組みが進んでいる一方で、相互作用界面の構造多様性をインタラクトーム規模で評価し、クラスタリングするための同等の手法はこれまで存在しなかった。本研究では、三次元の相互作用界面構造を検索可能な配列へと変換することで、タンパク質相互作用界面の高速なアラインメントとクラスタリングを可能にする手法、Foldseek-Interfaceを開発した。本手法は、最先端の既存ツールと同等の精度を示しながら、最大230倍高速に動作する。Foldseek-InterfaceをPDBに登録されているすべての生物学的アセンブリに適用した結果、310万の二量体を77,167個の相互作用界面クラスターに分類した。さらに、このリソースを用いて、相互作用界面の多様性、進化、および病原体による分子擬態の特徴を解析した。また、予測されたタンパク質複合体構造のデータベースにFoldseek-Interfaceを適用することで、これまで知られていない可能性のある新規な相互作用界面タイプを迅速に見いだすことができ、今後の実験的検証に値する候補を抽出できることを示した。Foldseek-Interfaceおよび相互作用界面クラスターのリソースは、検索用Webサーバー(https://search.foldseek.com/interface)および探索用Webサーバー(https://interface.foldseek.com)として無償で公開されている。
インストール
WSLで AVX2版 (GPU build)をダウンロードしてテストした。
Github
# Linux AVX2 build (check using: cat /proc/cpuinfo | grep avx2)
wget https://mmseqs.com/foldseek/foldseek-linux-avx2.tar.gz; tar xvzf foldseek-linux-avx2.tar.gz; export PATH=$(pwd)/foldseek/bin/:$PATH

# Linux AVX2 & GPU build (req. glibc >= 2.17 and nvidia driver >=525.60.13)
wget https://mmseqs.com/foldseek/foldseek-linux-gpu.tar.gz; tar xvfz foldseek-linux-gpu.tar.gz; export PATH=$(pwd)/foldseek/bin/:$PATH

# Linux ARM64 build
wget https://mmseqs.com/foldseek/foldseek-linux-arm64.tar.gz; tar xvzf foldseek-linux-arm64.tar.gz; export PATH=$(pwd)/foldseek/bin/:$PATH

#mamba (注;2026年9月1日現在のバージョンでは Foldseek-Interfaceには対応していない)
mamba create -n foldseek -y
conda activate foldseek
mamba install -c conda-forge -c bioconda foldseek -y
> foldseek
Foldseek enables fast and sensitive comparisons of large structure sets. It reaches sensitivities similar to state-of-the-art structural aligners while being at least 20,000 times faster.
Please cite:
van Kempen, M., Kim, S.S., Tumescheit, C., Mirdita, M., Lee, J., Gilchrist, C.L.M., Söding, J., and Steinegger, M. Fast and accurate protein structure search with Foldseek. Nature Biotechnology, doi:10.1038/s41587-023-01773-0 (2023)
foldseek Version: e28c8d2045b2603f192f20ffdc81b6084b53cc5d
© Michel van Kempen, Stephanie Kim, Charlotte Tumescheit, Milot Mirdita, Jeongjae Lee, Cameron L. M. Gilchrist, Johannes Söding, Martin Steinegger
usage: foldseek <command> [<args>]
Easy workflows for plain text input/output
easy-search Structual search
easy-cluster Slower, sensitive clustering
easy-rbh Find reciprocal best hit
easy-multimercluster Multimer level cluster
easy-interfacecluster Interface level cluster
easy-interfacesearch Interface level search
easy-multimersearch Multimer level search
Main workflows for database input/output
createdb Convert PDB/mmCIF/tar[.gz]/DB files or directory/TSV to a structure DB
search Sensitive homology search
rbh Reciprocal best hit search
cluster Slower, sensitive clustering
structureclusterupdate Update structure clustering with new sequences using structural alignment
multimercluster Multimer level cluster
interfacecluster Interface level cluster
interfacesearch Interface level search
multimersearch Multimer level search
Input database creation
databases List and download databases
createindex Store precomputed index on disk to reduce search overhead
createclusearchdb Build a searchable cluster database allowing for faster searches
Unite and intersect databases
createsubdb Create a subset of a DB from list of DB keys
createinterfacedb Create an interface DB of a dimer DB
createstructinterfacedb Create an interface DB of a dimer DB
createdimerdb Create a dimer DB of a DB
Format conversion for downstream processing
structty Launch StrucTTY viewer for foldseek results
convertalis Convert alignment DB to BLAST-tab, SAM or custom format
compressca Create a new C-alpha DB with chosen compression encoding from a sequence DB
convert2pdb Convert a foldseek structure db to a single multi model PDB/mmCIF file or a directory of PDB/mmCIF files
createmultimerreport Convert complexDB to tsv format
Prefiltering
expandmultimer Re-prefilter to ensure complete alignment between multimers
Alignment
tmalign Compute tm-score
lolalign LoLalign. creating structure alignmetns by optimizing the Local distance log odds (LoL) score
structurealign Compute structural alignment using 3Di alphabet, amino acids and neighborhood information
structurerescorediagonal Compute sequence identity for diagonal
aln2tmscore Compute tmscore of an alignment database
scoremultimer Get multimer level alignments from alignmentDB
Clustering
clust Cluster result by Set-Cover/Connected-Component/Greedy-Incremental
Profile databases
result2profile Compute profile DB from a result DB for both amino acid and 3di
>foldseek easy-interfacecluster -h
usage: foldseek easy-interfacecluster <i:PDB|mmCIF[.gz]> ... <i:PDB|mmCIF[.gz]> <o:clusterPrefix> <tmpDir> [options]
By Sooyoung Cha <ellen2g77@gmail.com>
options: prefilter:
--comp-bias-corr INT Correct for locally biased amino acid composition (range 0-1) [1]
--comp-bias-corr-scale FLOAT Correct for locally biased amino acid composition (range 0-1) [1.000]
--seed-sub-mat TWIN Substitution matrix file for k-mer generation [aa:3di.out,nucl:3di.out]
-s FLOAT Sensitivity: 1.0 faster; 4.0 fast; 7.5 sensitive [4.000]
-k INT k-mer length (0: automatically set to optimum) [0]
--target-search-mode INT target search mode (0: regular k-mer, 1: similar k-mer) [0]
--k-score TWIN k-mer threshold for generating similar k-mer lists [seq:2147483647,prof:2147483647]
--max-seqs INT Maximum results per query sequence allowed to pass the prefilter (affects sensitivity) [300]
--split INT Split input into N equally distributed chunks. 0: set the best split automatically [0]
--split-mode INT 0: split target db; 1: split query db; 2: auto, depending on main memory [2]
--split-memory-limit BYTE Set max memory per split. E.g. 800B, 5K, 10M, 1G. Default (0) to all available system memory [0]
--diag-score BOOL Use ungapped diagonal scoring during prefilter [1]
--exact-kmer-matching INT Extract only exact k-mers for matching (range 0-1) [0]
--mask INT Mask sequences in prefilter stage with tantan: 0: w/o low complexity masking, 1: with low complexity masking [0]
--mask-prob FLOAT Mask sequences is probablity is above threshold [1.000]
--mask-lower-case INT Lowercase letters will be excluded from k-mer search 0: include region, 1: exclude region [1]
--mask-n-repeat INT Repeat letters that occur > threshold in a rwo [6]
--min-ungapped-score INT Accept only matches with ungapped alignment score above threshold [30]
--spaced-kmer-mode INT 0: use consecutive positions in k-mers; 1: use spaced k-mers [1]
--spaced-kmer-pattern STR User-specified spaced k-mer pattern
--local-tmp STR Path where some of the temporary files will be created
--exhaustive-search BOOL Turns on an exhaustive all vs all search by by passing the prefilter step [1]
align:
--sort-by-structure-bits INT sort by bits*sqrt(alnlddt*alntmscore) [1]
-a BOOL Add backtrace string (convert to alignments with mmseqs convertalis module) [0]
--alignment-mode INT How to compute the alignment:
0: automatic
1: only score and end_pos
2: also start_pos and cov
3: also seq.id [0]
--alignment-output-mode INT How to compute the alignment:
0: automatic
1: only score and end_pos
2: also start_pos and cov
3: also seq.id
4: only ungapped alignment
5: score only (output) cluster format [0]
-e DOUBLE List matches below this E-value (range 0.0-inf) [1.000E+07]
--min-seq-id FLOAT List matches above this sequence identity (for clustering) (range 0.0-1.0) [0.000]
--min-aln-len INT Minimum alignment length (range 0-INT_MAX) [0]
--seq-id-mode INT 0: alignment length 1: shorter, 2: longer sequence [0]
--alt-ali INT Show up to this many alternative alignments [0]
-c FLOAT List matches above this fraction of aligned (covered) residues (see --cov-mode) [0.000]
--cov-mode INT 0: coverage of query and target
1: coverage of target
2: coverage of query
3: target seq. length has to be at least x% of query length
4: query seq. length has to be at least x% of target length
5: short seq. needs to be at least x% of the other seq. length [0]
--max-rejected INT Maximum rejected alignments before alignment calculation for a query is stopped [2147483647]
--max-accept INT Maximum accepted alignments before alignment calculation for a query is stopped [2147483647]
--gap-open TWIN Gap open cost [aa:10,nucl:10]
--gap-extend TWIN Gap extension cost [aa:1,nucl:1]
--min-assigned-chains-ratio FLOAT Minimum ratio of assigned chains out of all query chains > thr [0.0,1.0] [0.000]
--monomer-include-mode INT Monomer Complex Inclusion 0: include monomers, 1: NOT include monomers [0]
--expand-multimer-evalue DOUBLE E-value threshold for multimer chain expansion (range 0.0-inf) [1.000E+04]
clust:
--cluster-mode INT 0: Set-Cover (greedy)
1: Connected component (BLASTclust)
2,3: Greedy clustering by sequence length (CDHIT) [0]
--max-iterations INT Maximum depth of breadth first search in connected component clustering [1000]
--similarity-type INT Type of score used for clustering. 1: alignment score 2: sequence identity [2]
--set-mode BOOL 0: Cluster by each entry
1: Cluster by set [0]
kmermatcher:
--weights STR Weights used for cluster priorization
--cluster-weight-threshold FLOAT Weight threshold used for cluster priorization [0.900]
profile:
--mask-profile INT Mask query sequence of profile using tantan [0,1] [1]
--e-profile DOUBLE Include sequences matches with < E-value thr. into the profile (>=0.0) [1.000E-01]
--wg BOOL Use global sequence weighting for profile calculation [0]
--filter-msa INT Filter msa: 0: do not filter, 1: filter [1]
--filter-min-enable INT Only filter MSAs with more than N sequences, 0 always filters [0]
--max-seq-id FLOAT Reduce redundancy of output MSA using max. pairwise sequence identity [0.0,1.0] [0.900]
--qid STR Reduce diversity of output MSAs using min.seq. identity with query sequences [0.0,1.0]
Alternatively, can be a list of multiple thresholds:
E.g.: 0.15,0.30,0.50 to defines filter buckets of ]0.15-0.30] and ]0.30-0.50] [0.0]
--qsc FLOAT Reduce diversity of output MSAs using min. score per aligned residue with query sequences [-50.0,100.0] [-20.000]
--cov FLOAT Filter output MSAs using min. fraction of query residues covered by matched sequences [0.0,1.0] [0.000]
--diff INT Filter MSAs by selecting most diverse set of sequences, keeping at least this many seqs in each MSA block of length 50 [1000]
--pseudo-cnt-mode INT use 0: substitution-matrix or 1: context-specific pseudocounts [0]
--profile-output-mode INT Profile output mode: 0: binary log-odds 1: human-readable frequencies [0]
--num-iterations INT Number of iterative profile search iterations (0: auto (select optimal), 1: default, 1-n), N≥2 exactly N) [1]
misc:
--mask-bfactor-threshold FLOAT mask residues for seeding if b-factor < thr [0,100] [0.000]
--save-res-index BOOL Saves PDB residue indices of all residues in the input structures [0]
--input-format INT Format of input structures:
0: Auto-detect by extension
1: PDB
2: mmCIF
3: mmJSON
4: ChemComp
5: Foldcomp [0]
--input-compression-format INT Compression format of input structures:
0: Auto/File-ending based
1: gzip
2: zstd [0]
--file-include STR Include file names based on this regex [.*]
--file-exclude STR Exclude file names based on this regex [^$]
--tmscore-threshold FLOAT accept alignments with a tmsore > thr [0.0,1.0] [0.000]
--tmscore-threshold-mode INT 0: alignment, 1: query 2: target length [0]
--lddt-threshold FLOAT accept alignments with a lddt > thr [0.0,1.0] [0.200]
--alignment-type INT How to compute the alignment:
0: 3di alignment
1: TM alignment
2: 3Di+AA
3: LoL alignmnet [2]
--exact-tmscore INT turn on fast exact TMscore (slow), default is approximate [0]
--prefilter-mode INT prefilter mode: 0: kmer/ungapped 1: ungapped, 2: nofilter, 3: ungapped&gapped [0]
--tmalign-hit-order INT order hits by 0: (qTM+tTM)/2, 1: qTM, 2: tTM, 3: min(qTM,tTM) 4: max(qTM,tTM) [0]
--tmalign-fast INT turn on fast search in TM-align [1]
--lolalign-multidomain INT MultiDomain Mode LoLalign [1]
--candidate-seeds INT Number of candidate seeds to consider for expansion [10]
--refine-seeds INT Whether to refine seeds by re-aligning top candidate seeds and picking the best one for expansion [3]
--allow-deletion BOOL Allow deletions in a MSA [0]
--cluster-search INT first find representative then align all cluster members [0]
--interface-lddt-threshold FLOAT accept alignments with a lddt > thr [0.0,1.0] [0.000]
--chain-tm-threshold FLOAT accept alignments with a tmsore > thr [0.0,1.0] [0.000]
--multimer-tm-threshold FLOAT accept alignments with a multimer tmsore > thr [0.0,1.0] [0.400]
--min-aligned-chains INT save alignments with at least n chain aligned between query and target [2]
--distance-threshold FLOAT Residues with C-alpha below this threshold will be part of interface [10.000]
--min-interface-residues-perchain INT save dimer/interface if there are N numbers of residues per chain [4]
common:
--gpu INT Use GPU (CUDA) if possible [0]
--prostt5-model STR Path to ProstT5 model
--threads INT Number of CPU-cores used (all by default) [16]
-v INT Verbosity level: 0: quiet, 1: +errors, 2: +warnings, 3: +info [3]
--sub-mat TWIN Substitution matrix file [aa:3di.out,nucl:3di.out]
--max-seq-len INT Maximum sequence length [65535]
--db-load-mode INT Database preload mode 0: auto, 1: fread, 2: mmap, 3: mmap+touch [0]
--compressed INT Write compressed output [0]
--gpu-server INT Use GPU server [0]
--gpu-server-wait-timeout INT Wait for GPU server for 0: don't wait -1: no wait limit: >0 this many seconds [600]
--remove-tmp-files BOOL Delete temporary files [1]
--force-reuse BOOL Reuse tmp filse in tmp/latest folder ignoring parameters and version changes [0]
--mpi-runner STR Use MPI on compute cluster with this MPI command (e.g. "mpirun -np 42")
expert:
--chain-name-mode INT Add chain to name:
0: auto
1: always add
[0]
--model-name-mode INT Add model to name:
0: auto
1: always add
[0]
--write-mapping INT write _mapping file containing mapping from internal id to taxonomic identifier [0]
--write-foldcomp INT write _fcz Foldcomp database [0]
--coord-store-mode INT Coordinate storage mode:
1: C-alpha as float
2: C-alpha as difference (uint16_t) [2]
--write-lookup INT write .lookup file containing mapping from internal id, fasta id and file number [1]
--taxon-list STR Taxonomy ID, possibly multiple values separated by ','
--blocklen INT Block length for forward-backward [16]
--multimer-report-mode INT Complex report mode:
0: No report
1: Write complex report [1]
examples:
#Clustering of PDB files
foldseek easy-interfacecluster examples/ result tmp
# Cluster output
# - result_rep_seq.fasta: Representatives
# - result_cluster.tsv: Adjacency list
# Important parameter: --cov-mode and -c
# --cov-mode
# 0 1 2
# Q: MAVGTACRPA 60% IGN 60%
# T: -AVGTAC--- 60% 100% IGN
# -c 0.7 - + -
# -c 0.6 + + +
references:
- Kim, W., Mirdita, M., Levy Karin, E., Gilchrist, C.L.M., Schweke, H., Söding, J., Levy, E., and Steinegger, M. Rapid and sensitive protein complex alignment with Foldseek-Multimer. Nature Methods, doi:10.1038/s41592-025-02593-7 (2025)
> foldseek easy-interfacesearch -h
usage: foldseek easy-interfacesearch <i:PDB|mmCIF[.gz]> ... <i:PDB|mmCIF[.gz]>|<i:stdin> <i:targetFastaFile[.gz]>|<i:targetDB> <o:outputFileName> <tmpDir> [options]
By Sooyoung Cha <ellen2g77@gmail.com>
options: prefilter:
--comp-bias-corr INT Correct for locally biased amino acid composition (range 0-1) [1]
--comp-bias-corr-scale FLOAT Correct for locally biased amino acid composition (range 0-1) [1.000]
--seed-sub-mat TWIN Substitution matrix file for k-mer generation [aa:3di.out,nucl:3di.out]
-s FLOAT Sensitivity: 1.0 faster; 4.0 fast; 7.5 sensitive [4.000]
-k INT k-mer length (0: automatically set to optimum) [0]
--target-search-mode INT target search mode (0: regular k-mer, 1: similar k-mer) [0]
--k-score TWIN k-mer threshold for generating similar k-mer lists [seq:2147483647,prof:2147483647]
--max-seqs INT Maximum results per query sequence allowed to pass the prefilter (affects sensitivity) [300]
--split INT Split input into N equally distributed chunks. 0: set the best split automatically [0]
--split-mode INT 0: split target db; 1: split query db; 2: auto, depending on main memory [2]
--split-memory-limit BYTE Set max memory per split. E.g. 800B, 5K, 10M, 1G. Default (0) to all available system memory [0]
--diag-score BOOL Use ungapped diagonal scoring during prefilter [1]
--exact-kmer-matching INT Extract only exact k-mers for matching (range 0-1) [0]
--mask INT Mask sequences in prefilter stage with tantan: 0: w/o low complexity masking, 1: with low complexity masking [0]
--mask-prob FLOAT Mask sequences is probablity is above threshold [1.000]
--mask-lower-case INT Lowercase letters will be excluded from k-mer search 0: include region, 1: exclude region [1]
--mask-n-repeat INT Repeat letters that occur > threshold in a rwo [6]
--min-ungapped-score INT Accept only matches with ungapped alignment score above threshold [30]
--spaced-kmer-mode INT 0: use consecutive positions in k-mers; 1: use spaced k-mers [1]
--spaced-kmer-pattern STR User-specified spaced k-mer pattern
--local-tmp STR Path where some of the temporary files will be created
--exhaustive-search BOOL Turns on an exhaustive all vs all search by by passing the prefilter step [1]
align:
--sort-by-structure-bits INT sort by bits*sqrt(alnlddt*alntmscore) [1]
-a BOOL Add backtrace string (convert to alignments with mmseqs convertalis module) [0]
--alignment-mode INT How to compute the alignment:
0: automatic
1: only score and end_pos
2: also start_pos and cov
3: also seq.id [0]
--alignment-output-mode INT How to compute the alignment:
0: automatic
1: only score and end_pos
2: also start_pos and cov
3: also seq.id
4: only ungapped alignment
5: score only (output) cluster format [0]
-e DOUBLE List matches below this E-value (range 0.0-inf) [1.000E+07]
--min-seq-id FLOAT List matches above this sequence identity (for clustering) (range 0.0-1.0) [0.000]
--min-aln-len INT Minimum alignment length (range 0-INT_MAX) [0]
--seq-id-mode INT 0: alignment length 1: shorter, 2: longer sequence [0]
--alt-ali INT Show up to this many alternative alignments [0]
-c FLOAT List matches above this fraction of aligned (covered) residues (see --cov-mode) [0.000]
--cov-mode INT 0: coverage of query and target
1: coverage of target
2: coverage of query
3: target seq. length has to be at least x% of query length
4: query seq. length has to be at least x% of target length
5: short seq. needs to be at least x% of the other seq. length [0]
--max-rejected INT Maximum rejected alignments before alignment calculation for a query is stopped [2147483647]
--max-accept INT Maximum accepted alignments before alignment calculation for a query is stopped [2147483647]
--gap-open TWIN Gap open cost [aa:10,nucl:10]
--gap-extend TWIN Gap extension cost [aa:1,nucl:1]
--min-assigned-chains-ratio FLOAT Minimum ratio of assigned chains out of all query chains > thr [0.0,1.0] [0.000]
--monomer-include-mode INT Monomer Complex Inclusion 0: include monomers, 1: NOT include monomers [0]
--expand-multimer-evalue DOUBLE E-value threshold for multimer chain expansion (range 0.0-inf) [1.000E+04]
--view-structty BOOL Launch StrucTTY viewer after result generation (requires a build with -DENABLE_STRUCTTY=1) [0]
--structty-mode INT Color mode for the StrucTTY viewer:
0: protein
1: chain
2: rainbow
3: plddt
4: interface
5: conservation
6: align
7: align-fs
8: align-near [0]
--structty-ss BOOL Show secondary structure (helix/sheet) in the StrucTTY viewer [0]
profile:
--mask-profile INT Mask query sequence of profile using tantan [0,1] [1]
--e-profile DOUBLE Include sequences matches with < E-value thr. into the profile (>=0.0) [1.000E-01]
--wg BOOL Use global sequence weighting for profile calculation [0]
--filter-msa INT Filter msa: 0: do not filter, 1: filter [1]
--filter-min-enable INT Only filter MSAs with more than N sequences, 0 always filters [0]
--max-seq-id FLOAT Reduce redundancy of output MSA using max. pairwise sequence identity [0.0,1.0] [0.900]
--qid STR Reduce diversity of output MSAs using min.seq. identity with query sequences [0.0,1.0]
Alternatively, can be a list of multiple thresholds:
E.g.: 0.15,0.30,0.50 to defines filter buckets of ]0.15-0.30] and ]0.30-0.50] [0.0]
--qsc FLOAT Reduce diversity of output MSAs using min. score per aligned residue with query sequences [-50.0,100.0] [-20.000]
--cov FLOAT Filter output MSAs using min. fraction of query residues covered by matched sequences [0.0,1.0] [0.000]
--diff INT Filter MSAs by selecting most diverse set of sequences, keeping at least this many seqs in each MSA block of length 50 [1000]
--pseudo-cnt-mode INT use 0: substitution-matrix or 1: context-specific pseudocounts [0]
--profile-output-mode INT Profile output mode: 0: binary log-odds 1: human-readable frequencies [0]
--num-iterations INT Number of iterative profile search iterations (0: auto (select optimal), 1: default, 1-n), N≥2 exactly N) [1]
misc:
--mask-bfactor-threshold FLOAT mask residues for seeding if b-factor < thr [0,100] [0.000]
--save-res-index BOOL Saves PDB residue indices of all residues in the input structures [0]
--input-format INT Format of input structures:
0: Auto-detect by extension
1: PDB
2: mmCIF
3: mmJSON
4: ChemComp
5: Foldcomp [0]
--input-compression-format INT Compression format of input structures:
0: Auto/File-ending based
1: gzip
2: zstd [0]
--file-include STR Include file names based on this regex [.*]
--file-exclude STR Exclude file names based on this regex [^$]
--tmscore-threshold FLOAT accept alignments with a tmsore > thr [0.0,1.0] [0.000]
--tmscore-threshold-mode INT 0: alignment, 1: query 2: target length [0]
--lddt-threshold FLOAT accept alignments with a lddt > thr [0.0,1.0] [0.200]
--alignment-type INT How to compute the alignment:
0: 3di alignment
1: TM alignment
2: 3Di+AA
3: LoL alignmnet [2]
--exact-tmscore INT turn on fast exact TMscore (slow), default is approximate [0]
--prefilter-mode INT prefilter mode: 0: kmer/ungapped 1: ungapped, 2: nofilter, 3: ungapped&gapped [0]
--tmalign-hit-order INT order hits by 0: (qTM+tTM)/2, 1: qTM, 2: tTM, 3: min(qTM,tTM) 4: max(qTM,tTM) [0]
--tmalign-fast INT turn on fast search in TM-align [1]
--lolalign-multidomain INT MultiDomain Mode LoLalign [1]
--candidate-seeds INT Number of candidate seeds to consider for expansion [10]
--refine-seeds INT Whether to refine seeds by re-aligning top candidate seeds and picking the best one for expansion [3]
--allow-deletion BOOL Allow deletions in a MSA [0]
--cluster-search INT first find representative then align all cluster members [0]
--interface-lddt-threshold FLOAT accept alignments with a lddt > thr [0.0,1.0] [0.000]
--chain-tm-threshold FLOAT accept alignments with a tmsore > thr [0.0,1.0] [0.000]
--multimer-tm-threshold FLOAT accept alignments with a multimer tmsore > thr [0.0,1.0] [0.400]
--min-aligned-chains INT save alignments with at least n chain aligned between query and target [2]
--format-mode INT Output format:
0: BLAST-TAB
1: SAM
2: BLAST-TAB + query/db length
3: Pretty HTML
4: BLAST-TAB + column headers
5: Calpha only PDB super-posed to query
BLAST-TAB (0) and BLAST-TAB + column headers (4)support custom output formats (--format-output)
(5) Superposed PDB files (Calpha only) [0]
--format-output STR Choose comma separated list of output columns from: query,target,evalue,gapopen,pident,fident,nident,qstart,qend,qlen
tstart,tend,tlen,alnlen,raw,bits,cigar,qseq,tseq,q3di,t3di,qheader,theader,qaln,taln,q3dialn,t3dialn,mismatch,qcov,tcov
qset,qsetid,tset,tsetid,taxid,taxname,taxlineage,
lddt,lddtfull,qca,tca,t,u,qtmscore,ttmscore,alntmscore,rmsd,prob
complexqtmscore,complexttmscore,complexu,complext,qcomplexcoverage,tcomplexcoverage,qchaintms,tchaintms,qchains,tchains,interfacelddt,complexassignid
qkey,tkey
[query,target,fident,alnlen,mismatch,gapopen,qstart,qend,tstart,tend,evalue,bits]
--distance-threshold FLOAT Residues with C-alpha below this threshold will be part of interface [10.000]
--min-interface-residues-perchain INT save dimer/interface if there are N numbers of residues per chain [4]
common:
--gpu INT Use GPU (CUDA) if possible [0]
--threads INT Number of CPU-cores used (all by default) [16]
-v INT Verbosity level: 0: quiet, 1: +errors, 2: +warnings, 3: +info [3]
--sub-mat TWIN Substitution matrix file [aa:3di.out,nucl:3di.out]
--max-seq-len INT Maximum sequence length [65535]
--db-load-mode INT Database preload mode 0: auto, 1: fread, 2: mmap, 3: mmap+touch [0]
--compressed INT Write compressed output [0]
--gpu-server INT Use GPU server [0]
--gpu-server-wait-timeout INT Wait for GPU server for 0: don't wait -1: no wait limit: >0 this many seconds [600]
--remove-tmp-files BOOL Delete temporary files [1]
--force-reuse BOOL Reuse tmp filse in tmp/latest folder ignoring parameters and version changes [0]
--mpi-runner STR Use MPI on compute cluster with this MPI command (e.g. "mpirun -np 42")
expert:
--chain-name-mode INT Add chain to name:
0: auto
1: always add
[0]
--model-name-mode INT Add model to name:
0: auto
1: always add
[0]
--write-mapping INT write _mapping file containing mapping from internal id to taxonomic identifier [0]
--write-foldcomp INT write _fcz Foldcomp database [0]
--coord-store-mode INT Coordinate storage mode:
1: C-alpha as float
2: C-alpha as difference (uint16_t) [2]
--write-lookup INT write .lookup file containing mapping from internal id, fasta id and file number [1]
--taxon-list STR Taxonomy ID, possibly multiple values separated by ','
--blocklen INT Block length for forward-backward [16]
--multimer-report-mode INT Complex report mode:
0: No report
1: Write complex report [1]
--db-output BOOL Return a result DB instead of a text file [0]
examples:
# Search a single/multiple PDB file's interface against a set of PDB files and get interface-multimer level alignments
foldseek easy-interfacesearch example/1tim.pdb.gz example/8tim.pdb.gz result tmp
# Format output differently
foldseek easy-interfacesearch example/1tim.pdb.gz example/8tim.pdb.gz result tmp --format-output query,target,qstart,tstart,cigar
# Align with TMalign (global)
foldseek easy-interfacesearch example/1tim.pdb.gz example/8tim.pdb.gz result tmp --alignment-type 1
# Skip prefilter and perform an exhaustive alignment (slower but more sensitive)
foldseek easy-interfacesearch example/1tim.pdb.gz example/8tim.pdb.gz result tmp --exhaustive-search 1
references:
- Kim, W., Mirdita, M., Levy Karin, E., Gilchrist, C.L.M., Schweke, H., Söding, J., Levy, E., and Steinegger, M. Rapid and sensitive protein complex alignment with Foldseek-Multimer. Nature Methods, doi:10.1038/s41592-025-02593-7 (2025)
実行方法
foldseek easy-interfacecluster
複数のタンパク質複合体構造からタンパク質同士が接触している界面を抽出し、似た界面ごとにクラスタリングする。PDBかmmCIF(.cif、.mmcif)ファイルをディレクトリに集めて実行する。
foldseek easy-interfacecluster structures/ interface_clusters tmp/ --threads 8
出力例

interface_clusters_rep_seq.fasta
interface_clusters_cluster.tsv

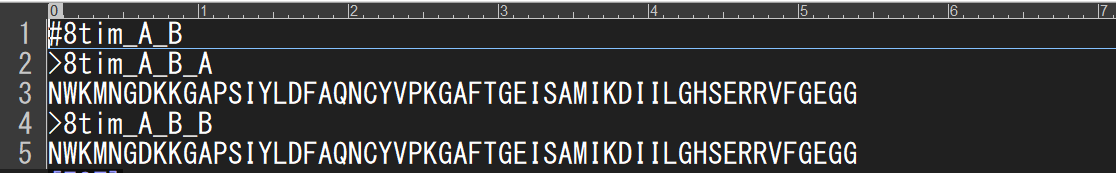
exampleにある2つのPDBファイルを使って相互作用の界面に基づくクラスタリングをすると、8tim_A_Bを代表とする1つのクラスタができ、その中に2構造とも含まれた。
foldseek easy-interfacesearch
界面を検索するには、クエリ構造と検索対象の構造データベースを指定する。対象データベースを何度も検索する場合は、あらかじめ構造データベースを作成しておく。
foldseek createdb structures/ targetDB
foldseek easy-interfacesearch query.pdb targetDB interface_hits.tsv tmp/ --threads 8
出力例
界面クラスタリングでは、代表界面とメンバーの対応を示すクラスタTSV、代表配列をまとめたFASTA、界面アラインメントのレポートなどが生成される。検索では、クエリと対象、アラインメント長、E-value、スコア、界面の類似度に関する情報をタブ区切りで取得できる。

interface_search.tsv
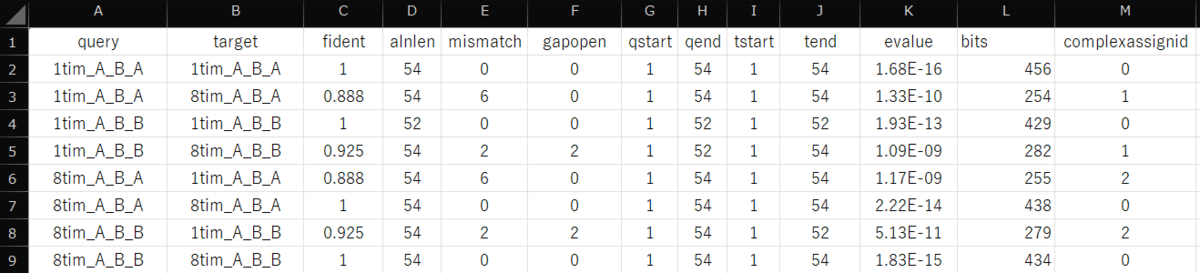
複数のタンパク質複合体から抽出した相互作用界面同士を比較し、類似する界面同士の検索結果をタブ区切りで記録したファイルとなる。各行には、比較した界面、配列一致率、整列長、E-value、スコアなどが含まれる。
検索感度、E-value、被覆率、界面LDDTを指定する。
foldseek easy-interfacesearch query.pdb targetDB
interface_hits.tsv tmp/ -s 4 -e 1e-3 --interface-lddt-threshold 0.65
- --interface-lddt-threshold accept alignments with a lddt > thr [0.0,1.0] [0.000]
- -s Sensitivity: 1.0 faster; 4.0 fast; 7.5 sensitive [4.000]
- -e List matches below this E-value (range 0.0-inf)
-s 4は検索感度を指定している。値を大きくすると遠い構造類似も拾いやすくなる。-e 1e-3は、E-valueが0.001未満の結果だけを出力する。--interface-lddt-threshold 0.65は、界面LDDTが0.65を超える検索結果だけを出力する。
Foldseek Search Server - PDB/mmCIFの複合体構造をアップロードして、その複合体界面と似た界面をPDBから探すことができる。
https://search.foldseek.com/interface

従来のFoldseekはタンパク質単体や複合体の類似した立体構造を検索する。コレに対して、Foldseek-Interfaceは2つのタンパク質鎖が接触している相互作用界面だけを取り出し、その界面構造を検索する。
Protein Interface Clusters - クラスタリング用のWebサービス
https://interface.foldseek.com

Protein Interface Clustersは、PDB全体をFoldseek-Interfaceでクラスタリングして作った既知タンパク質界面の分類データベース。プレプリントでは、PDB由来の約310万dimers(相互作用している2本のポリペプチド鎖のペア)を最終的に 77,167 interface clusters に分類し、そのクラスターを探索用Webサーバーとして公開している。
検索結果の例
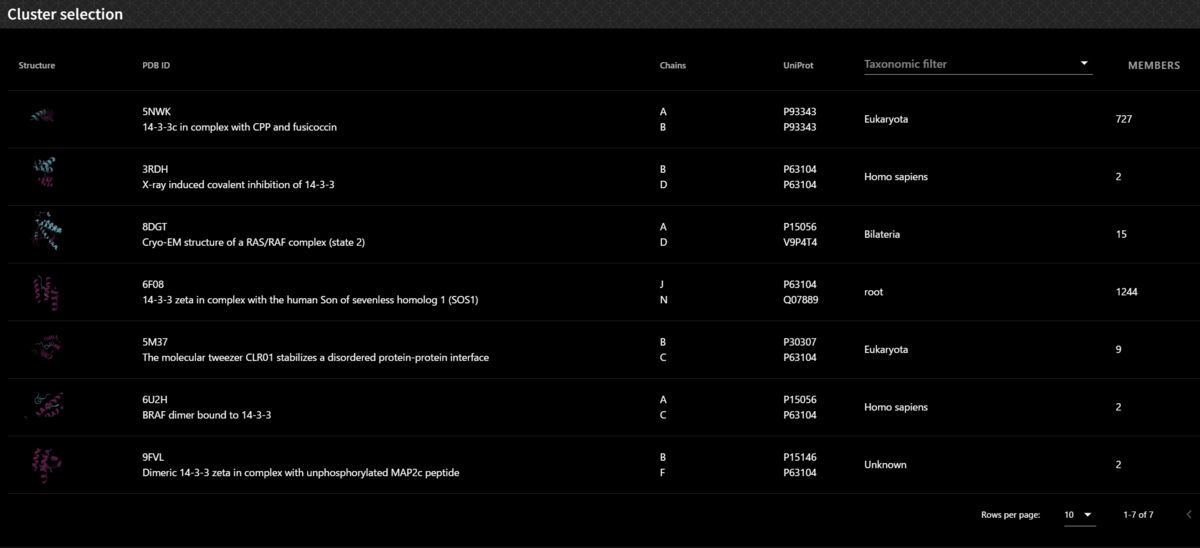
検索結果には、類似した相互作用界面をもつPDB構造が並び、それぞれについて PDB ID、相互作用しているchain、UniProt ID、分類群、同じinterface clusterに含まれる構造数が表示される。この例では14-3-3関連タンパク質を含む複数の複合体構造がヒットしている。重要なのは、タンパク質全体の構造が似ているかではなく、2つのタンパク質が接触している部分の形や配置が似ているものがまとめて検索されるという点である。
MEMBERSは、その界面と同じタイプに分類されたPDB中のinterfaceが何件あるかを示す。したがって、この結果を見ることで、自分が入力した複合体の結合様式が既知構造の中でどの程度一般的なのか、またどのようなタンパク質で同じような結合様式が使われているのかを確認できる。
クラスタを選択すると、その相互作用界面についてさらに詳しい情報を確認できる (その結合様式をもつ構造がどれだけ存在し、どの生物に分布し、どのようなタンパク質同士で使われているか)。

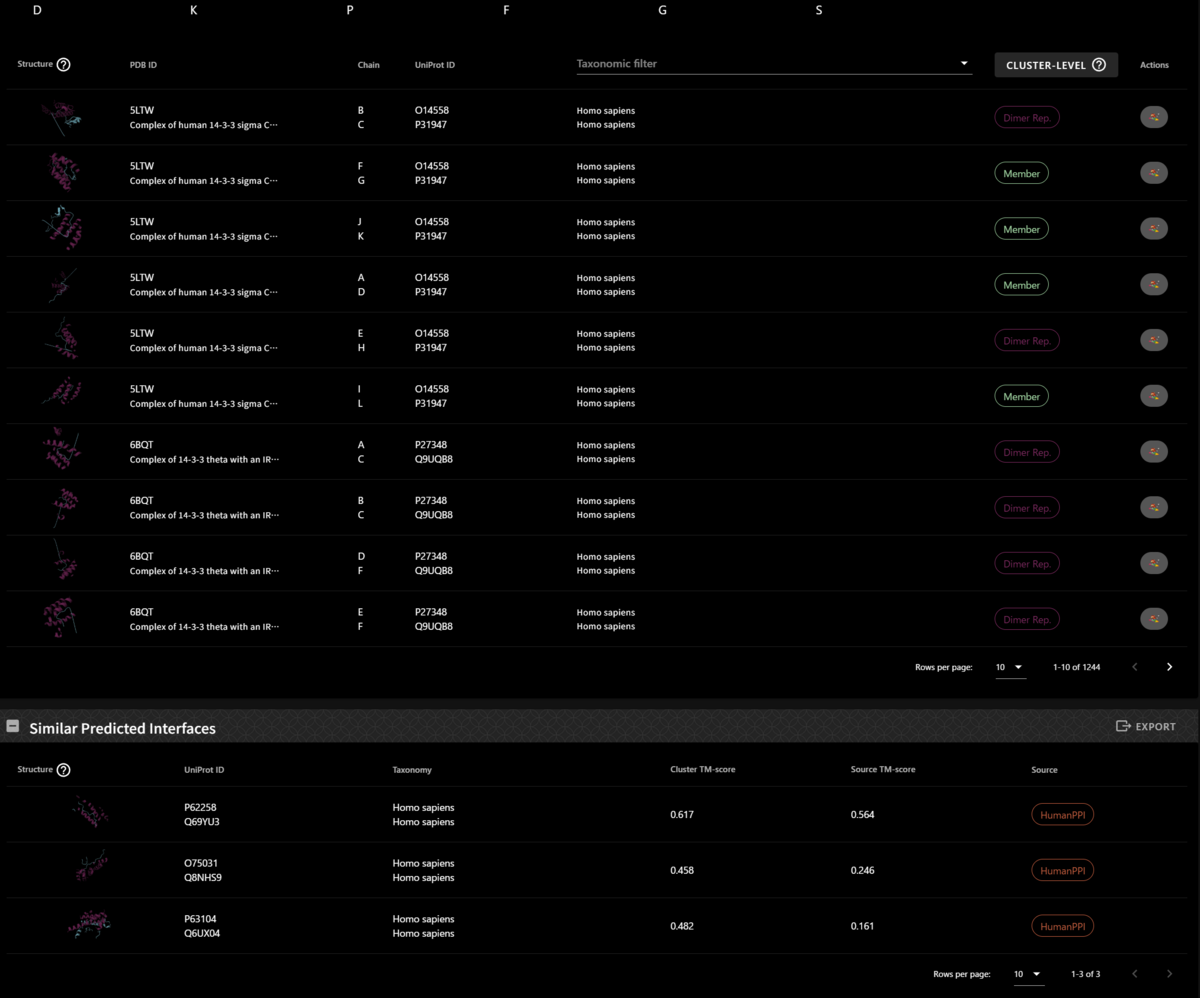
この例では Cluster 43749830 に1244件のinterfaceが含まれており、代表構造として14-3-3 zetaとSOS1の複合体(PDB: 6F08)が表示されている。さらに、このクラスタでは どのような二次構造が界面を構成しているか、また 秩序のある構造どうしの相互作用か、天然変性領域を含む相互作用か といった特徴もまとめられている。下部には、このクラスタに含まれるinterfaceがどの生物群に分布しているかが系統分類に沿って表示される。Cluster membersでは、同じinterface clusterに分類された個々のPDB構造を一覧できる。Similar Predicted Interfacesには、PDBの実験からの構造だけでなく、HumanPPIなどの予測複合体データから、このclusterと類似したinterfaceも表示される。類似度はTM-scoreとともに示される。
その他、論文より
-
タンパク質には、独立して折りたたまれ三次構造を形成する領域(秩序領域、ordered regions)(1)と、単独の状態では構造を形成せず、天然変性領域(intrinsically disordered regions; IDRs)と呼ばれる領域(2)が存在する。秩序だったタンパク質領域同士やコイルドコイルを介した相互作用は、安定な複合体や剛直な足場構造を形成する。一方、天然変性領域が関与する相互作用では、しばしば短い直鎖状モチーフが相手タンパク質の秩序領域に結合し、一過性のシグナル伝達複合体の形成や凝縮体形成を媒介する(3)。
-
類似した相互作用界面構造は、複合体全体としては互いに無関係なタンパク質の間にも、収斂進化によって生じ得る(7)。そのため、共通する結合様式を見いだすには、複合体全体を比較するのではなく、相互作用界面そのものを直接比較する必要がある。また、界面構造の類似性に基づいてクラスタリングすることで、既知のインタラクトームを繰り返し現れるトポロジー上のファミリーとして整理できると考えられる(8, 9)。
-
本研究では、相互作用界面を高速かつ高精度にアラインメントする手法Foldseek-Interfaceを開発した。この手法では、抽出した界面残基を各鎖内でN末端からC末端の順に並べ直して新たに番号を付けることで、界面の非連続性という問題を解決する。これによって連続した3Di文字列を生成し、Foldseekで直接アラインメントできるようにする。一方で、対応する鎖の組み合わせの同定にはFoldseek-Multimerを用いる。さらに、界面部分だけを対象として算出したTM-score(interface-only TM-score)(20)の閾値に基づき、データベース規模で界面をクラスタリングするためのフレームワークも構築した。
-
この手法をPDBに登録されているすべてのbiological assemblyに適用した結果、310万個のタンパク質二量体を77,167個の非冗長な相互作用界面クラスターへ分類した。これらは、それぞれ異なる界面タイプを表すものと考えられる。また、タンパク質フォールドの新規発見が飽和しつつある一方で、新しい相互作用界面の発見は現在も続いていることを示した。
- Foldseek-Interfaceを用いることで、病原体タンパク質が宿主のタンパク質間相互作用を構造的に模倣する例を網羅的に探索できる。実際の解析では、ヒト–ヒトPPIとヒト–病原体PPIで類似した界面を共有する候補が56クラスター見つかり、その多くはウイルス由来であった。特にdisordered regionを介した相互作用が多く、短いモチーフを利用して宿主タンパク質との結合を乗っ取るウイルスの戦略とよく一致する。PPI界面の類似性から、病原体による宿主分子の「なりすまし」を探索できる。
- Foldseek-Interfaceは、PDBに登録された実験構造だけでなく、大規模に予測されたPPI構造の整理にも利用できる。HumanPPIで予測された約2.1万のヒトPPIを解析したところ、10,040の界面クラスターに分類され、そのうち1,780クラスターではPDB中に類似した既知界面が見つからなかった。実験的にまだ観測されていない新しい結合様式が多数含まれる可能性がある (大量のPPI予測結果から、既知の界面とは異なる候補を効率よく絞り込める)。
- タンパク質全体の構造が似ていなくても、相互作用界面に共通した形状や残基配置があれば、機能的に似た結合様式の候補として見つけられる可能性がある。Foldseek-Interfaceは、この界面を検索の中心にしている。
- 実用面では、既知のPDB構造から界面の候補を探すだけでなく、AlphaFold-Multimerなどで予測したタンパク質複合体を検索し、既知の界面クラスタに属するか、あるいは新しい界面タイプらしいかを調べられる。
- Foldseek-Interfaceは、タンパク質全体ではなく、2本のタンパク質鎖が接触する相互作用界面を単位として検索・分類する。複数のPDB/mmCIF構造を入力して界面を抽出し、界面レベルでクラスタリングする場合はeasy-interfaceclusterを使う。
引用
Foldseek-Interface reveals a protein interface universe far from complete
Joelle Morgan Strom, Sooyoung Cha, Rachel Seongeun Kim, Harshit Sajal, Cameron L. M. Gilchrist, Martin Steinegger & Katja Luck
bioRxiv, Posted August 25, 2026.
関連
参考
Foldseek-Interface reveals a protein interface universe far from complete
— Biology+AI Daily (@BiologyAIDaily) August 31, 2026
1 Foldseek-Interface introduces an interface-specific structural encoding: it extracts contacting residues from both partners (Cα distance ≤10 Å; ≥4 residues per chain), renumbers them in N-to-C order… pic.twitter.com/VCYk5cbjMR
